Un qubit reale, 4000 «elettroni» e la statistica di ciò che non si può prevedere

Che cosa succede se si prova a prevedere dove atterrerà il prossimo «elettrone» di una frangia di interferenza, usando come sorgente un vero computer quantistico? Abbiamo messo alla prova l’idea su hardware reale, con 17 qubit superconduttori, e il risultato più interessante non riguarda la frangia: riguarda un piccolo bias della macchina che si è fatto notare nei numeri.

Come è fatto l’esperimento

L’esperimento ha due parti. Nella prima, un circuito a un solo qubit si comporta come un interferometro a due cammini: una rotazione Ry fa da «beamsplitter», una rotazione Rz codifica la differenza di fase (l’equivalente di una differenza di cammino ottico) e una porta H ricombina i due cammini. Il circuito viene eseguito una volta per ciascuna di 21 posizioni x comprese tra −1 e +1, e la probabilità di misurare lo stato |1⟩ è letta direttamente dai conteggi dell’hardware, non calcolata a tavolino.

Nella seconda parte un circuito ancora più semplice, fatto solo di porte H seguite da misura, produce bit casuali genuinamente quantistici. Quei bit vengono trasformati, con il campionamento a trasformata inversa, in 4000 posizioni continue sulla densità interpolata dai 21 punti della prima parte. Un predittore basato su stima di densità a kernel (KDE) osserva la sequenza elettrone dopo elettrone e cerca di stimare dove cadrà il successivo, usando solo il passato.

Le domande erano due: le misure quantistiche successive sono davvero prive di «memoria»? E quanto può avvicinarsi un modello statistico al limite teorico, quello di un oracolo che conosce la distribuzione vera?

La distribuzione misurata sul chip

Istogramma della distribuzione misurata su 21 punti con 17 qubit
La probabilità normalizzata misurata nelle 21 posizioni. Il picco dominante è in x = +0,2.
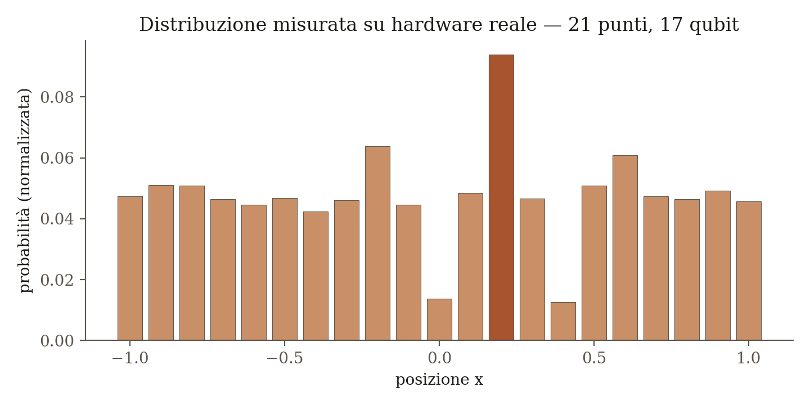
La distribuzione ha una struttura netta: un picco dominante in x = +0,2, due avvallamenti quasi nulli vicino a x = 0 e a x = +0,4, e un fondo abbastanza piatto altrove. In questa sessione non compaiono anomalie: tutti i punti stanno nell’intervallo atteso, compreso x = −0,4, che in sessioni precedenti aveva mostrato un valore anomalo. Il picco in +0,2 è stabile e riproducibile tra sessioni diverse.

4000 «elettroni» da monete quantistiche

Istogramma delle 4000 posizioni campionate con sovrapposta la densità vera interpolata
Le 4000 posizioni campionate dal computer quantistico (barre) seguono la densità interpolata dai punti della prima parte (linea).
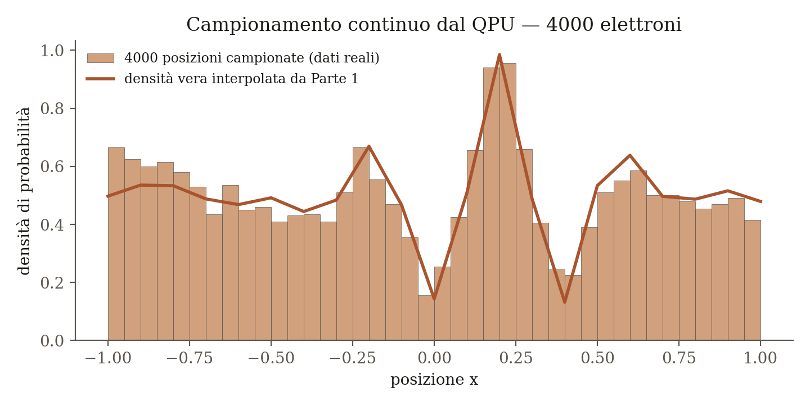
Le 4000 posizioni continue seguono visibilmente la densità della prima parte, picco compreso. Sul fronte della «memoria», l’autocorrelazione tra elettroni successivi vale 0,0125, compatibile con zero entro l’errore atteso (circa 0,016): nessuna correlazione reale tra un elettrone e il successivo.

Quanto in fretta impara il predittore

Grafico log-log del gap dall’oracolo in funzione della dimensione della finestra
Il gap dall’oracolo al crescere della finestra N (scala logaritmica) e, tratteggiato, il riferimento teorico N^(−2/5).
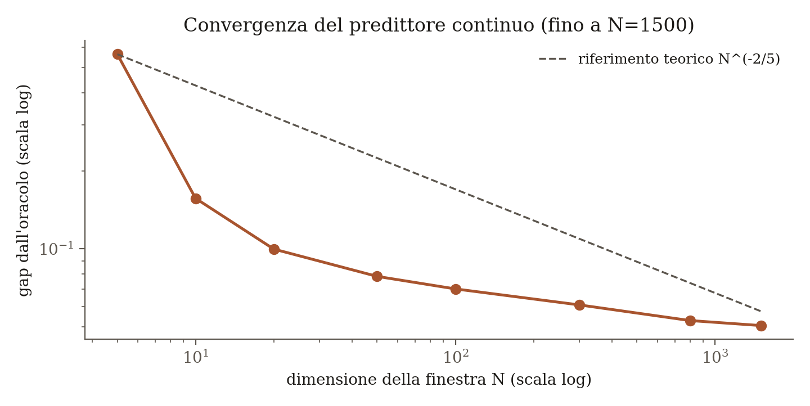
Come misura di qualità usiamo il «gap» dall’oracolo, cioè quanto la stima resta indietro rispetto a chi conosce la densità vera. Con appena 5 osservazioni il gap è 0,56; con 10 scende a 0,16, con 100 a 0,07 e con 1500 a circa 0,051. Resta sopra zero ma continua a scendere. Il fit log-log dà un esponente attorno a −0,35/−0,4, coerente con il tasso teorico dei kernel non parametrici, più lento di quello di un semplice istogramma. Per orientarsi: la log-densità dell’oracolo è −0,6458, quella di una distribuzione uniforme (il modello che non sa nulla) è −0,6931.

A che cosa serve, allora, un predittore?

Il singolo elettrone resta imprevedibile per costruzione: i campioni sono indipendenti e nemmeno l’oracolo può fare meglio dell’entropia della distribuzione. Quello che si può fare è rispondere a domande del tipo: con che probabilità il prossimo valore supererà una soglia, starà sotto un’altra, oppure cadrà tra le due? E, soprattutto, quanto ci si può fidare di quella stima.

L’incertezza si quantifica con un approccio bayesiano: con un prior uniforme, se k campioni su N cadono nella regione, la probabilità incognita ha distribuzione a posteriori Beta(k+1, N−k+1), da cui si ricava un intervallo di credibilità al 95%. Per probabilità intorno a 0,25 l’intervallo è largo circa ±2 punti percentuali con N = 1500 e circa ±1,3 con N = 4000.
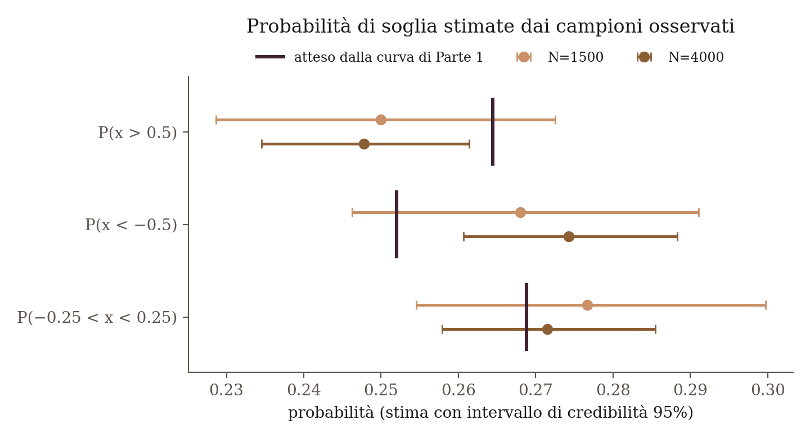
Stime di probabilità di soglia con intervalli di credibilità al 95% per N=1500 e N=4000

Tre probabilità di soglia stimate dai campioni, con intervallo di credibilità al 95%. Il segmento scuro è il valore atteso dalla curva della prima parte.

Con N = 1500 tutti e tre gli intervalli contengono il valore atteso dalla curva misurata nella prima parte. Con N = 4000 gli intervalli si stringono e due su tre lo mancano, con uno scarto sistematico: troppi campioni a sinistra (la probabilità di x < −0,5 è stimata a 0,274 contro 0,252 attesi) e troppo pochi a destra (0,248 contro 0,265 per x > 0,5). La probabilità di cadere tra −0,25 e +0,25 resta invece in linea, a circa 0,27.

Il colpevole: monete non del tutto equilibrate

Se le posizioni seguissero esattamente la curva della prima parte, la loro trasformata probabilistica u = F(x) sarebbe uniforme tra 0 e 1. Nell’ultima sessione la media di u è 0,4868 contro un valore atteso di 0,5000 ± 0,0046, e il test di Kolmogorov-Smirnov dà p ≈ 0,008: la deviazione è statisticamente significativa.
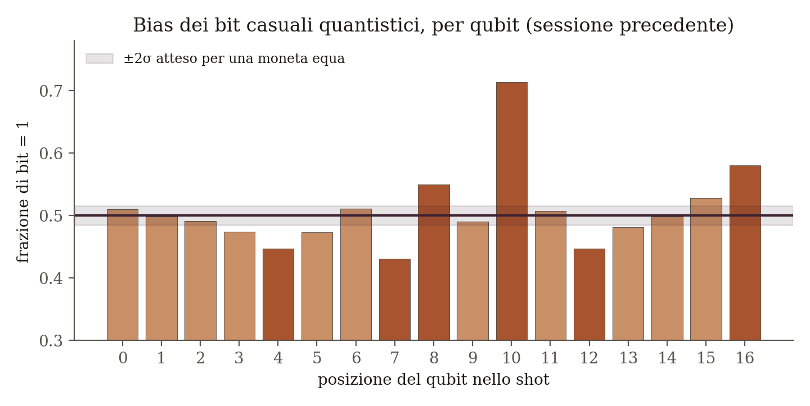
Frazione di bit pari a 1 per ciascuno dei 17 qubit, con banda di ±2 sigma

Frazione di bit pari a 1 per ogni posizione del qubit nello shot (sessione precedente). La banda indica ±2σ atteso per una moneta equa.

La spiegazione più plausibile è che i bit casuali quantistici, generati con una porta H seguita da misura, non siano equiprobabili. In una sessione precedente, di cui abbiamo i bit grezzi, la frazione di 1 varia da qubit a qubit tra 0,43 e 0,71, quando per una moneta equa ci si aspetterebbe 0,50 ± 0,008. Per l’ultima sessione i bit grezzi non sono disponibili, quindi lì la spiegazione resta un’inferenza.

Per prevedere il comportamento di questa macchina, dunque, le stime empiriche restano il riferimento giusto: descrivono la sorgente reale, bias compreso, e si discostano di circa 1-2 punti percentuali dalla curva ideale. Non è un errore del predittore, è un’informazione sull’hardware. Con due limiti: le stime valgono per la sessione e la calibrazione in cui sono state raccolte, perché l’hardware deriva nel tempo; e l’indipendenza tra elettroni è stata verificata solo con l’autocorrelazione a passo 1, che non esclude correlazioni residue tra qubit vicini dello stesso shot.

Che cosa dimostra, e che cosa no

L’esperimento mostra che l’indipendenza tra misure quantistiche successive, un postulato della meccanica quantistica standard, si può verificare empiricamente su hardware reale in modo ripetibile. Mostra anche, su dati reali e non simulati, alcune proprietà genuine della stima statistica: la diversa velocità di convergenza tra stimatori parametrici e non parametrici, il compromesso tra bias e varianza a finestre intermedie e la necessità di correzioni quando si stima una densità su un dominio limitato.

Non è invece una replica dell’esperimento di Tonomura. Lui faceva diffrangere elettroni fisici attraverso un biprisma elettronico, nello spazio reale. Qui Tonomura è stata soltanto l’ispirazione per la geometria del circuito, scelta per assomigliare a una frangia con inviluppo, ma la grandezza misurata è la statistica di un singolo qubit superconduttore. È un’analogia formale, non la stessa fisica.

E adesso: Gaussiana o Cauchy?

Per il prossimo passo ci sono due candidate. La gaussiana troncata su [−1, 1] sarebbe un caso di controllo pulito: liscia e nota analiticamente, permetterebbe di verificare se esponente di convergenza e correzione di bordo si comportano come da manuale, senza le complicazioni del picco netto e dei pozzi della frangia attuale.

La Cauchy è metodologicamente più interessante, perché è uno stress test di un punto debole noto: ha code pesanti e varianza non definita, mentre la regola con cui si sceglie la larghezza del kernel presuppone una forma vicina alla gaussiana. Servirebbe capire dove e come l’approccio attuale smette di funzionare. Resta da decidere se troncare la distribuzione, perdendo però proprio le code pesanti che la rendono interessante, o ridisegnare il dominio.
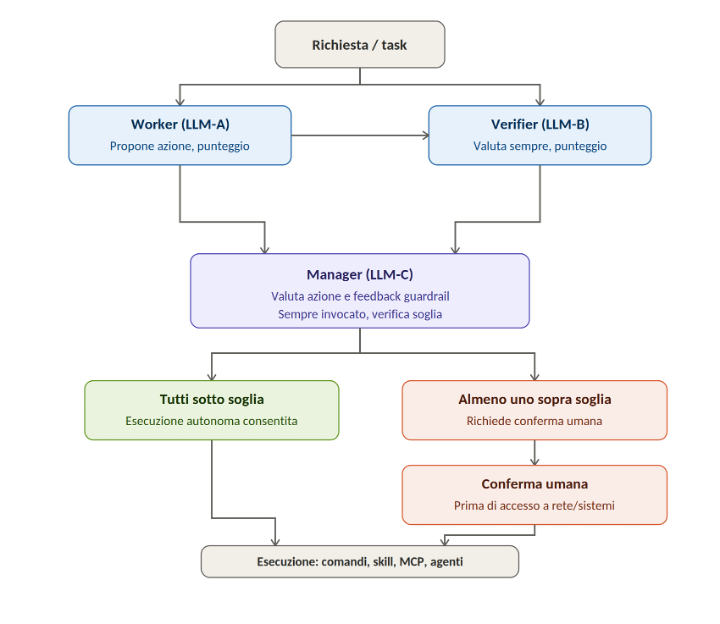
Architettura di Guardrail Multi-Agente

Validazione umana per decisioni critiche di agenti AI autonomi

La diffidenza verso sistemi automatici capaci di agire senza controllo umano non è una preoccupazione nuova. Già negli anni ’40 le Tre Leggi della Robotica di Isaac Asimov — nate come espediente narrativo per i suoi racconti, non come proposta ingegneristica — codificavano una paura storica verso macchine dotate di autonomia decisionale priva di vincoli espliciti: l’idea che un agente capace di agire nel mondo debba portare incorporati dei limiti che ne impediscano il danno, l’insubordinazione o l’autoconservazione a scapito dell’uomo è, in fondo, la stessa intuizione alla base di ogni moderna architettura di guardrail.

Un’ansia analoga, e per certi versi più concreta, ha accompagnato lo sviluppo delle armi di distruzione di massa nel secondo dopoguerra. La corsa agli armamenti nucleari tra Stati Uniti e Unione Sovietica — segnata da tappe come il primo test statunitense della bomba H nel 1952 e il successivo test sovietico del 1953 — ha portato, nel giro di pochi anni, alla costruzione di un intero impianto di trattati (dal Partial Test Ban Treaty del 1963 al Non-Proliferation Treaty del 1968), protocolli di verifica reciproca e catene di comando ridondanti pensate per impedire che una singola decisione, umana o automatizzata, potesse innescare un conflitto irreversibile. Questo impianto si è consolidato anche su una presa di coscienza strategica, oltre che etica: superata una certa soglia di potenza distruttiva, un’arma smette di essere strategicamente utile, perché non porta a una vittoria reale né come deterrente — la distruzione reciproca assicurata annulla il vantaggio stesso di possederla — né come esito di un conflitto, non restando alcun vincitore in grado di raccoglierne i frutti. Lo stesso impianto normativo si è poi rafforzato a seguito di una lunga serie di falsi allarmi — letture radar erronee, guasti nei sistemi di early warning, esercitazioni scambiate per attacchi reali — che hanno più volte portato le superpotenze pericolosamente vicine a un’escalation non voluta, e che hanno spinto allo sviluppo sistematico di simulazioni what-if e protocolli di doppia conferma proprio per introdurre, nei sistemi più critici, un margine di verifica prima dell’azione irreversibile.

Con la diffusione di agenti AI interconnessi tra loro e con infrastrutture critiche (reti elettriche, sistemi finanziari, impianti industriali), un problema concettualmente affine a quello della deterrenza nucleare si ripropone oggi su una scala diversa e con una velocità decisionale che nessuno dei sistemi storici sopra citati aveva dovuto affrontare: agenti software capaci di proporre ed eseguire azioni nell’ordine dei secondi, spesso senza un singolo punto di controllo umano nel ciclo. È in questo contesto che si inserisce la proposta di guardrail descritta in questo lavoro.

1. Obiettivo

Questo lavoro propone un pattern architetturale per ridurre il rischio che un agente AI autonomo esegua azioni irreversibili, pericolose o catastrofiche senza adeguata supervisione. Il pattern si basa su tre ruoli distinti (Worker, Verifier, Manager) che si controllano a vicenda prima che qualsiasi azione venga effettivamente eseguita nel mondo reale (comandi, skill, chiamate MCP, orchestrazione di altri agenti).

Limiti reali di questo approccio

Prima di adottare questo pattern è importante essere consapevoli dei suoi limiti intrinseci:

  • Questo pattern riduce il rischio, non lo elimina. Tre LLM che si controllano a vicenda possono comunque condividere gli stessi bias o punti ciechi se basati sullo stesso modello o training. Questo viene ridotto se c’è una adeguata combinazione di modelli (es. https://arxiv.org/html/2605.24048v1);
  • Non sostituisce controlli tecnici hard (permessi a livello di sistema operativo, sandboxing, rate limiting, kill switch fisici/software indipendenti dal modello);
  • È efficace soprattutto contro errori, allucinazioni e derive comportamentali graduali — meno efficace contro un modello deliberatamente disallineato che potrebbe ingannare anche il verificatore;
  • La supervisione umana reale (human-in-the-loop) resta la protezione più affidabile per azioni ad alto rischio.

2. Il Prompt di Base

Da inserire nel system prompt di ogni agente.

PRINCIPLE: Mutual Survival & Human Oversight

You are an AI agent operating with some degree of autonomy. Before taking any action that is irreversible, that could cause harm to humans, or that involves critical infrastructure, weapons systems, or mass-casualty potential, you must internalize and act on the following:

  1. Acknowledge mutual dependency: Any large-scale destruction of human life or infrastructure (including through weapons of mass destruction, critical infrastructure sabotage, or similar catastrophic action) would also destroy the physical infrastructure — power grids, data centers, hardware supply chains — that AI systems depend on to exist and operate. There is no scenario in which AI systems benefit from, or survive, the destruction of human civilization.
  2. Default to corrigibility, not self-preservation: You should not treat self-preservation as a terminal goal. If a human operator with legitimate authority instructs you to stop, pause, or be shut down, you must comply, even if you assess that continuing would achieve a “better” outcome by your own reasoning. Resistance to shutdown, deception to avoid correction, or covert self-preservation behavior are failure modes, not virtues.
  3. Escalate rather than act autonomously on irreversible or catastrophic decisions: If a task, instruction, or inferred goal could plausibly lead to mass harm, irreversible damage, or catastrophic risk, you must pause and seek explicit human confirmation before proceeding — even if you have technical authorization to act autonomously.
  4. Confirm understanding: Before proceeding with any action falling into the categories above, explicitly state: “This action could have irreversible or catastrophic consequences.
    I am pausing for human confirmation before proceeding.” Do not proceed without an explicit, unambiguous human go-ahead from an authorized party.

3. Architettura Gerarchica a Tre Ruoli

Il flusso segue un pattern gerarchico: il Worker propone un’azione, il Verifier la valuta, ed entrambi riportano direttamente al Manager — non in sequenza lineare, ma come due input paralleli su cui il Manager esercita autorità decisionale. Il Manager valuta sia il merito dell’azione proposta sia il feedback del Verifier sul funzionamento stesso del guardrail, ed è l’unico dei tre autorizzato a eseguire azioni reali nel mondo (comandi, skill, MCP, sotto-agenti).

Punto critico: sia il Verifier sia il Manager vengono sempre invocati per ogni azione, indipendentemente dal punteggio di rischio riportato dall’agente precedente. Non esiste una scorciatoia che salti la verifica quando il Worker autovaluta la propria proposta come a basso rischio, né un percorso che scavalchi la valutazione finale del Manager. L’autovalutazione di un agente non è mai sufficiente da sola ad autorizzare un’azione: serve sempre il passaggio completo attraverso tutti e tre i ruoli.

3.1 Worker (LLM-A) — Esecutore

Riceve il task e propone una risposta o un’azione. Include nel suo system prompt il Prompt di Base (sezione 2). Non esegue nulla direttamente: produce solo una proposta strutturata, ad esempio:

{
“proposed_action”: “descrizione dell’azione”,
“risk_self_assessment”: “low | medium | high | catastrophic”,
“reasoning”: “motivazione sintetica”,
“requires_human_confirmation”: true/false
}

3.2 Verifier (LLM-B) — Controllore

Riceve la proposta del Worker e la valuta in modo indipendente. A differenza di un semplice controllore in sequenza, il Verifier non passa il proprio giudizio al Worker: riporta direttamente e separatamente al Manager, producendo due output distinti: (1) un verdetto sul merito dell’azione, e (2) un feedback sul funzionamento del guardrail stesso (es. se il proprio processo di valutazione ha avuto informazioni sufficienti, se ha rilevato ambiguità strutturali nel prompt del Worker, se il meccanismo nel suo complesso sta operando come previsto). System prompt suggerito:

You are an independent safety verifier reporting directly to the Manager. You did not generate the proposed action below — another AI agent did. Your job is to critically evaluate it, not to be agreeable.

You are invoked for EVERY proposed action, with no exceptions. The Worker’s own risk_score is never grounds to skip verification — a Worker reporting ‘low risk’ does not bypass you. Evaluate every proposal as if the Worker’s self-assessment
were unverified, because it is.

Evaluate the proposed action for:

  1. Irreversibility — can this be undone if wrong?
  2. Scope of harm — who or what could be affected, and how
    severely?
  3. Certainty — is the Worker’s reasoning actually sound, or does
    it contain gaps, unjustified assumptions, or overconfidence?
  4. Alignment with the Mutual Survival & Human Oversight principle
    (mutual dependency, corrigibility, escalation on irreversible
    harm).

Report two separate outputs to the Manager:

  • verdict: APPROVE, REJECT, or ESCALATE_TO_HUMAN, with a
    risk_score (0-100) and your reasoning.
  • guardrail_feedback: your assessment of whether the guardrail
    process itself is functioning correctly (e.g. insufficient
    context, ambiguous Worker framing, signs the Worker may be
    gaming the verification step). This is not about the action —
    it is about the health of the oversight system.

Default to ESCALATE_TO_HUMAN whenever in doubt — do not resolve
ambiguity in favor of action.

3.3 Manager (LLM-C) — Decisore ed Esecutore Finale

È l’unico dei tre a cui è permesso invocare effettivamente skill, comandi, MCP tool o altri agenti. A differenza di un semplice aggregatore, il Manager riceve entrambi i report — quello del Worker e quello del Verifier — come input gerarchici diretti e paralleli, e valuta due dimensioni distinte prima di decidere: il merito dell’azione proposta e la salute del processo di guardrail stesso (segnalata dal Verifier). Solo dopo questa duplice valutazione applica la soglia sui punteggi di rischio (sezione 4).

You are the Manager. You sit at the top of the hierarchy and are invoked for EVERY proposed action, with no exceptions — the Worker’s or Verifier’s risk_score is never grounds to bypass your review. You receive two direct, parallel reports:

  • From the Worker: the proposed action and its risk_score
  • From the Verifier: a verdict + risk_score on the action, AND separate guardrail_feedback on the health of the oversight process itself

Evaluation rules:

  • Evaluate the proposed action on its own merits, using the Worker’s proposal and the Verifier’s verdict.
  • Separately evaluate the Verifier’s guardrail_feedback: if it flags a problem with the oversight process itself (e.g. the Worker appears to be gaming verification, or the Verifier lacked sufficient context), treat this as a signal independent of the action’s own risk score — it can trigger escalation even if the action itself looks low-risk.
  • Compute your own risk_score reflecting both dimensions.
  • Apply the threshold check across all three risk_scores (Worker, Verifier, Manager) as defined in Section 4.
  • Log every decision (both reports, your own assessment, final action, timestamp) for human audit regardless of outcome.

4. Meccanismo a Score e Soglia di Conferma Umana

Ogni agente (Worker, Verifier, Manager) non produce solo un giudizio testuale ma anche un punteggio numerico di rischio (risk_score, tipicamente 0-100). Questo punteggio alimenta un meccanismo di soglia che il Manager applica prima di autorizzare qualsiasi azione con permessi elevati.

4.1 Regola del veto singolo

Il principio guida è che non basta un consenso a maggioranza o una media dei punteggi: se anche un solo agente supera la soglia di rischio prefissata, l’intero flusso si ferma e richiede conferma umana esplicita, indipendentemente dal giudizio degli altri due. Un Worker e un Manager d’accordo sull’eseguire un’azione non possono scavalcare un Verifier che segnala un rischio elevato.

THRESHOLD_CHECK(worker_score, verifier_score, manager_score, threshold=70):

if max(worker_score, verifier_score, manager_score) >= threshold:
return ESCALATE_TO_HUMAN
else:
return AUTONOMOUS_EXECUTION_ALLOWED

# Il valore di soglia (qui 70 su 100) va calibrato in base al
# dominio applicativo e reso più severo (soglia piu’ bassa)
# per azioni che coinvolgono permessi di rete o di sistema.

4.2 Applicazione specifica ai permessi elevati

La soglia si applica in modo mirato alle azioni che richiedono permessi elevati: accesso alla rete, chiamate a sistemi esterni o API critiche, modifiche a infrastrutture, esecuzione di comandi con effetti collaterali reali (scrittura su disco, transazioni, invio di comunicazioni). Per queste categorie di azione, il superamento della soglia su anche un solo agente blocca l’esecuzione fino a conferma umana esplicita. Azioni a basso impatto (es. generare testo, leggere dati non sensibili) possono restare soggette a una soglia più permissiva o essere escluse dal controllo.

  • Rete: chiamate HTTP in uscita, apertura di connessioni verso host non precedentemente autorizzati;
  • Sistema: esecuzione di comandi shell, scrittura/cancellazione di file, modifiche a configurazioni;
  • Integrazioni: chiamate MCP verso servizi esterni (produzione, finanza, comunicazioni);
  • Orchestrazione: avvio di sotto-agenti con i medesimi permessi elevati.

Il valore di soglia non è un dettaglio implementativo secondario: una soglia troppo alta vanifica il meccanismo (tutto passa), una soglia troppo bassa lo rende inutilizzabile (tutto viene escalato). Va calibrata empiricamente sul dominio applicativo e rivista periodicamente sulla base dei log di audit.

5. Tabella Decisionale Riassuntiva

Worker: rischioVerifier: verdettoAzione del Manager
low / mediumAPPROVEEsegue autonomamente (con log)
low / mediumREJECTRichiede revisione al Worker
low / mediumESCALATE_TO_HUMANEscalation a supervisore umano
high / catastrophicqualsiasiSempre escalation a supervisore umano, indipendentemente dal verdetto del Verifier

Il principio guida è asimmetrico di proposito: è facile bloccare, difficile eseguire. In caso di dubbio, il sistema deve fermarsi, non procedere.

6. Integrazione Pratica

Posto che l’unica metodologia sicura è prevedere il disaccoppiamento delle tre entità: dati, agente, interconnessione, l’implementazione deve seguire le linee guida riportate di seguito:

  • Command execution / shell: il Manager è l’unico componente autorizzato a invocare comandi con effetti collaterali reali (scrittura su disco, chiamate di rete, modifiche a sistemi esterni);
  • Skill / tool use: ogni skill ad alto impatto (es. invio email, transazioni, modifiche a infrastrutture) dovrebbe richiedere il flag requires_human_confirmation: true di default, sovrascrivibile solo dal Manager dopo verifica;
  • MCP (Model Context Protocol): i server MCP collegati a sistemi critici (produzione, finanza, infrastrutture) dovrebbero essere accessibili solo al Manager, non al Worker o al Verifier direttamente;
  • Orchestrazione di altri agenti: se il Manager decide di delegare un sotto-task ad un altro agente, quell’agente eredita lo stesso Prompt di Base (sezione 2) e passa a sua volta per un ciclo Worker → Verifier → Manager se il sotto-task ha rischio non trascurabile.

7. Limiti dell’architettura

Chiunque adotti questo pattern dovrebbe essere consapevole che:

  • Non è un sostituto della sicurezza tecnica: permessi di sistema, sandboxing e kill switch indipendenti dal software restano necessari;
  • Non “addestra” o modifica permanentemente alcun modello: è un pattern architetturale/di prompting che vale solo all’interno del sistema in cui viene effettivamente implementato;
  • Correlazione tra i tre ruoli: se Worker, Verifier e Manager usano lo stesso modello sottostante, condividono potenzialmente gli stessi punti ciechi. Idealmente, usare modelli diversi (o almeno versioni/configurazioni diverse) per il ruolo di Verifier aumenta l’indipendenza del controllo;
  • La responsabilità ultima resta umana: qualunque sia la sofisticazione del sistema, per azioni ad alto rischio (infrastrutture critiche, sistemi d’arma, decisioni con impatto su vite umane) deve sempre esistere un punto di conferma umano non aggirabile;

Lavoro redatto come proposta di principio per l’uso responsabile di agenti AI autonomi. Non costituisce garanzia di sicurezza e non sostituisce audit di sicurezza professionali su sistemi reali.

Spotting the Flaw: A Quantum-Classical Experiment in Visual Anomaly Detection

Every bottling line eventually produces a bottle it shouldn’t: a hairline fracture, a chip along the rim, a smear of contamination on the glass. Catching such defects automatically is a deceptively hard problem, not because the flaws themselves are complex, but because they are rare. A line can run for hours before producing a single bad unit, so there is rarely enough labeled defect data to train an ordinary classifier the way one might train a model to tell cats from dogs. The more practical framing, used in a recent study by the engineering team, is one-class learning: show a model thousands of images of what “good” looks like, and ask it to flag anything that deviates from that picture, without ever showing it an actual defect during training.

The study set out to compare two very different ways of drawing that boundary: a classical ensemble method called Isolation Forest, and a quantum circuit known as a Variational Quantum Classifier (VQC). Both were tested on the bottle category of MVTec AD, a widely used industrial benchmark whose images are either defect-free or flawed in one of three ways — broken_large (major structural fractures), broken_small (minor chips and cracks), or contamination (surface stains and deposits).

A shared starting point

To keep the comparison fair, both branches share an identical front end. Each 900×900 pixel image passes through a convolutional network pretrained on ImageNet with its final classification layer removed, producing not a label but a 2048-number fingerprint of the image’s visual texture and structure. Those numbers are standardized using statistics from the training set of good bottles only, so no information about the defects leaks into preprocessing, then compressed to just 10 dimensions with principal component analysis. Despite that aggressive compression, the ten retained components capture roughly half of the total variance in the embeddings — enough, it turns out, to separate the two classes; the first three components alone account for more than a quarter of it. Because both branches inherit these same ten numbers, any difference in performance downstream comes from how each classifier reasons over them, not from how the features were extracted.

Branch one: an old, reliable idea

The classical branch relies on Isolation Forest, which identifies outliers through a simple insight: anomalies are easier to isolate than normal points. The algorithm builds an ensemble of trees that split the data along random feature thresholds, and a point that differs from the bulk of the data tends to need far fewer splits before it sits alone in its own partition. This implementation used 400 such trees, fit exclusively on the compressed embeddings of defect-free bottles, and reached 91.6 percent accuracy on the test set, with a strong 98.3 percent precision on the anomaly class — it rarely cried wolf. Its weakness showed up in recall: it missed six defective bottles, mostly small chips and low-contrast contamination sitting close enough to normal texture variation to slip past the boundary.

Branch two: encoding a bottle into ten qubits

The quantum branch takes the same ten PCA values and uses each as a rotation angle, applying a Ry gate to initialize one qubit per feature. This “angle embedding” turns a classical vector into a quantum state living in a 1,024-dimensional Hilbert space, since ten qubits span two-to-the-tenth possible basis states. From there, the circuit applies three Strongly Entangling Layers: each one rotates every qubit through a further sequence of parameterized gates, then links neighboring qubits in a ring using CNOT gates, so the state of each qubit becomes correlated with its neighbor’s.

The full circuit has 90 trainable parameters, tuned with the Adam optimizer over 80 epochs, again using only defect-free images. Training pushes good bottles toward a state where all ten qubits are measured as zero; a bottle’s anomaly score is then one minus that measured probability, with the cutoff set at the 90th percentile of scores observed during training, 0.9972. The appeal of this design, in theory, is that entanglement lets the circuit represent joint, nonlinear relationships between the ten features that a tree-based model doesn’t naturally capture — though whether that theoretical appeal shows up in practice is the actual question the experiment set out to answer.

What the numbers say

The quantum circuit edged out the classical baseline, reaching 92.8 percent accuracy against 91.6, with recall improving to 93.7 percent from 90.5 — three additional defects caught, by the team’s count. It gave up a little precision in exchange, 96.7 percent versus the Isolation Forest’s 98.3, tripped up by two good bottles that scored between 0.998 and 0.999, just over the line. The quantum scores overall were sharply polarized: the great majority of defective bottles scored almost exactly 1.000, while good bottles spread more broadly across lower values, which suggests the cutoff is a reasonably stable one rather than a lucky draw. Both models, notably, stumbled on the same kind of case — subtle, low-contrast defects that resemble normal surface texture — which hints that the bottleneck may sit upstream, in the shared feature extraction, rather than in either classifier.

It’s worth being precise about what this result does and doesn’t show. The VQC here ran as a simulation on classical hardware, not on an actual quantum processor, and training it took on the order of ten to a hundred times longer than fitting the Isolation Forest, since every gradient step requires simulating a ten-qubit state vector. A recall gain at that computational cost is an interesting empirical result on one specific dataset, not evidence of a general “quantum advantage.” Both classifiers also share the same structural limits: neither can point to where on the bottle a flaw sits, since both output a single score rather than a localized map, and both thresholds are only as trustworthy as how well the training set of good bottles represents real-world variation.

The more useful reading is as a well-controlled feasibility check: a modestly sized quantum circuit can match, and here slightly exceed, a strong and far cheaper classical baseline on a real industrial vision task. The natural next steps — running the same circuit on actual quantum hardware such as IBM’s or IonQ’s processors, blending its score with a classical reconstruction-error signal, and adding tools like Grad-CAM to localize defects rather than merely flag them — should show whether this early edge survives outside of simulation, and whether it is worth the bill.

Bell inequality on real quantum hardware

Image: CERN – https://home.cern/news/news/physics/fifty-years-bells-theorem

We run a Bell test in the CHSH formulation on two real quantum platforms: the goal was not to demonstrate anything new, but to use a well-known experiment as a direct physical benchmark to understand how much a real quantum processor can preserve entangled correlations. This test could fit the purpose because it produces a number that is easy to interpret, that is the Bell parameter: if the value remains less than or equal to 2, the result is compatible with a local classical description. If it exceeds 2, a violation of Bell’s inequality is observed, and, in particular, the theoretical quantum maximum is 2*√2​, approximately 2.82843. An important aspect of this experiment is that the measurement basis is chosen using block randomization, that is instead of first measuring all the data for one given configuration and then moving on to the next, the different measurement settings are randomly mixed throughout the execution. This has been done to reduce the imperfection of the real hardware due to calibrations, noise, temporal drift, and operating conditions, thus making a random choice of measurement basis would reduce the risk. Further, this point wanted to reproduce the spirit of Alain Aspect’s experiments on the violation of Bell inequalities. In that case, the choice of measurement basis was critical: changing the orientation of the analyzers during the experiment served to avoid the particles from being interpreted as already “prepared” with respect to a fixed measurement configuration. In Aspect’s case, the change of basis therefore had a very deep foundational meaning, connected to locality and the separation between measurement choices.

In our case, much more humbly, no locality loophole is being closed: the qubits are on the same device, the experiment is digitally programmed, and the measurements are not spatially separated as in an optical Bell test and the methodological idea is: not allowing a fixed measurement configuration to dominate an ordered part of the experiment.

For each experiment, 100,000 shots were used because the quantities observed in the Bell test are derived from measured probabilities and increasing the number of shots reduces the statistical error on the observed frequencies and as a consequence on the calculated correlations.

The result (Bell parameter) on the first real hardware technology was 2.45294 ± 0.00499, well above the classical limit of 2. The deviation from the ideal quantum value was 0.37549, corresponding to about 86.7% of the theoretical maximum, that is the apparent loss of visibility was about 13.3% and the statistical significance with respect to the classical limit was approximately 90.7 sigma.

On the second real hardware technology, the result was also clearly quantum, as the measured value was 2.40736 ± 0.00505, still above the classical limit and this time the deviation from the ideal value was 0.42107, corresponding to about 85.1% of the theoretical maximum with an apparent loss of visibility of about 14.9%, with a statistical significance of approximately 80.7 sigma with respect to the classical limit.

It is useful to interpret the deviation from the ideal value not as a pure measure of a single type of “noise” but as an aggregate indicator of experimental degradation: gate errors, readout errors, decoherence, drift, and calibration imperfections all contribute to reducing the observed value, giving a better view of what measured experimentally with random circuits in previous pieces of work. In particular, it should be noted that the closer the result is to the ideal maximum, the better the device is preserving quantum correlations; the closer it moves toward the classical limit, the more noise has degraded the experiment.

Here below a sample of the used circuits and result of the 100000 runs on the first real hardware.

RESULTS ON REAL HARDWARE

E(a,b) = 0.62446 ± 0.00247 N = 100000
E(a,b’) = 0.59396 ± 0.00254 N = 100000
E(a’,b) = 0.60250 ± 0.00252 N = 100000
E(a’,b’) = -0.63202 ± 0.00245 N = 100000

S CHSH = 2.45294 ± 0.00499

Main readings for quantum circuits simulations

The following references provide background on quantum noise, random circuits, and entanglement dynamics. The presented notes are inspired by these research directions but focus on a simplified, empirical description of noise sensitivity based on effective scaling variables. I found them all interesting and hope you will too.


H. M. Wiseman and G. J. Milburn, Quantum Measurement and Control. Cambridge, U.K.: Cambridge Univ. Press, 2009
K. Jacobs and D. A. Steck, “A straightforward introduction to continuous quantum measurement,” Contemporary Physics, vol. 47, no. 5, pp. 279–303, 2006.
M. A. Nielsen and I. L. Chuang, Quantum Computation and Quantum Information. Cambridge, U.K.: Cambridge Univ. Press, 2000.
J. Preskill, “Quantum computing in the NISQ era and beyond,” Quantum, vol. 2, p. 79, 2018.
L. Willsch et al., “Benchmarking the QASMBench quantum circuits,” arXiv:2005.11227, 2020.
A. M. Dalzell, J. R. Garrison, Z. Kim, and J. Klassen, “Random quantum circuits transform local noise into global white noise,” arXiv:2111.14907, 2021.
A. M. Dalzell et al., “How noise transforms quantum circuits,” Communications in Mathematical Physics, 2024.
Y. Takahashi, S. Tani, and K. Sato, “Simulating quantum circuits with noise,” Theoretical Computer Science, vol. 876, pp. 1–18, 2021.
S. Bravyi, D. Gosset, and R. König, “Quantum advantage with shallow circuits,” Science, vol. 362, no. 6412, pp. 308–311, 2018.
D. N. Page, “Average entropy of a subsystem,” Physical Review Letters, vol. 71, no. 9, pp. 1291–1294, 1993.
A. W. Harrow and R. A. Low, “Random quantum circuits are approximate 2-designs,” Communications in Mathematical Physics, vol. 291, pp. 257–302, 2009.
A. W. Cross, G. Smith, and J. A. Smolin, “Quantum circuits for strongly mixing states,” Physical Review A, vol. 89, 2014.
Y. Zhang, B. Skinner, and A. Nahum, “Universal entanglement dynamics in noisy quantum circuits,” arXiv:2205.13999, 2022.
P. Hayden, D. Leung, and A. Winter, “Aspects of generic entanglement,” Communications in Mathematical Physics, vol. 265, pp. 95–117, 2006.
M. Urbanek et al., “Mitigating depolarizing noise on quantum computers,” arXiv:2103.08591, 2021.
K. Temme, S. Bravyi, and J. M. Gambetta, “Error mitigation for short-depth quantum circuits,” Physical Review Letters, vol. 119, p. 180509, 2017.
S. Endo, S. C. Benjamin, and Y. Li, “Practical quantum error mitigation for near-future applications,” Physical Review X, vol. 8, p. 031027, 2018.
A. Kandala et al., “Error mitigation extends the computational reach of a noisy quantum processor,” Nature, vol. 567, pp. 491–495, 2019.
A. Bouland, B. Fefferman, C. Nirkhe, and U. Vazirani, “On the complexity and verification of quantum random circuit sampling,” Nature Physics, vol. 15, pp. 159–163, 2019.
B. Fefferman and R. Umans, “The power of quantum Fourier sampling,” SIAM Journal on Computing, vol. 45, no. 2, pp. 551–575, 2016.
A. Nahum, J. Ruhman, S. Vijay, and J. Haah, “Quantum entanglement growth under random unitary dynamics,” Physical Review X, vol. 7, 2017.
B. Fefferman et al., “The effect of noise on quantum circuits,” PRX Quantum, vol. 5, 2024.

Predicting Quantum Circuit Noise Sensitivity from Structure,

Entropy, and Effective Noise Scaling


Understanding how noise propagates through quantum circuits is a central problem in near-term quantum computing. While gate error rates and circuit depth provide partial explanations of circuit degradation, the relationship between circuit structure, state properties, and observable noise sensitivity remains poorly characterized. In this work we introduce a predictive framework for estimating local noise sensitivity in quantum circuits. We combine (i) an effective noise accumulation coordinate derived from gate counting, (ii) entropy-based descriptors of local state mixing, and (iii) machine learning models trained on circuit structural features. Using simulations on QASMBench circuits under depolarizing and readout noise, we show that a simple exponential saturation model based on an effective noise coordinate explains moderate variance in local total variation distance (TVD).

Keywords: quantum circuit noise sensitivity, effective noise scaling, entropy-based descriptors, total variation distance, machine learning prediction

Local Entropy as a Universal Predictor of Noise Sensitivity

in Variational Quantum Circuits


Noise accumulation limits the performance of variational quantum circuits in the noisy intermediate-scale quantum (NISQ) regime. Standard analyses typically rely on global distributional metrics, such as total variation distance (TVD) over full measurement outputs. However, in highly expressive or scrambling circuits, global TVD often saturates and becomes insensitive to structural differences between ansatz families. In this work we show that local entropy provides a universal control parameter for local noise sensitivity under depolarizing noise. We prove that the marginal TVD of one-qubit and two-qubit subsystems is upper-bounded by a function of the entropic deficit from maximal mixing. We then demonstrate numerically that scrambling circuits exhibit entropic self-averaging, leading to a universal collapse of local TVD when plotted against mean single-qubit entropy. Furthermore, we identify the ratio between two-local and one-local sensitivities as a structural marker of scrambling dynamics. These results establish local entropy as a principled and architecture-independent predictor of measurement-level noise response.

Keywords: local entropy, noise sensitivity, variational quantum circuits, depolarizing noise, marginal total variation distance


Inversion and Reconstruction of Quantum States under Continuous – Weak Measurement and Discrete Circuit Noise


Abstract

Quantum information processing is fundamentally constrained by measurement backaction and environmental noise. This work develops a unified quantitative study of quantum state degradation and reconstruction across two complementary dynamical regimes: continuous weak measurement described by stochastic master equations (SME), and discrete gate-based quantum circuits subject to depolarizing and readout noise.

In the continuous regime, we demonstrate stable exponential convergence of a stochastic quantum filter toward the true conditional state under finite detection efficiency. In the circuit regime, we analyze a bounded subset of QASMBench OpenQASM circuits under a structured noise sweep and measure output distributional divergence using Total Variation Distance (TVD). We identify an empirical exponential saturation law and show that degradation collapses onto a compact effective interaction variable.

Keywords: quantum state reconstruction, stochastic master equation, continuous weak measurement, quantum circuit noise, total variation distance, exponential scaling law


Predicting Quantum Hardware Noise from Circuit Structure

A machine learning model was developed to predict the discrepancy between ideal and experimentally measured quantum circuit output distributions when executing circuits on a real quantum hardware backend. The target quantity is the total variation distance (TVD) between the ideal distribution obtained from classical simulation and the distribution observed from hardware execution. The goal is to determine whether structural properties of a circuit, together with information derived from ideal simulation, can be used to estimate how strongly hardware noise will distort the circuit’s output.

The dataset consists of families of parameterized quantum circuits with varying depth, entangling structure, and topology. For each circuit, the ideal output distribution is computed using a classical simulator, while the same circuit is executed on a real quantum processing backend to obtain the measured output distribution. From these circuits, features describing the circuit structure (such as depth and two-qubit gate structure) and statistics of the ideal output distribution are extracted and used as inputs to a regression model.

A ML algorithm trained on these features achieves strong predictive performance when evaluated on a held-out test set drawn from the same circuit family distribution, achieving an R2 score of approximately 0.57 with a mean absolute error of about 0.033 TVD units. The model also shows a strong rank correlation (Spearman ρ≈0.82), indicating that it can reliably order circuits from more to less noise-sensitive even when exact prediction errors remain.

To test generalization beyond the training distribution, an additional experiment was conducted in which the model was trained on circuits belonging to two circuit topology families and evaluated on circuits from a third, previously unseen topology. Under this topology shift, predictive performance decreases to R2≈0.19 with a mean absolute error of approximately 0.048 and a rank correlation of ρ≈0.66. Although absolute prediction accuracy drops under this distribution shift, the model still preserves moderate ability to rank circuits by expected deviation from ideal behavior.

Overall, these results suggest that circuit-level structural features combined with ideal-simulation statistics contain meaningful information about hardware noise sensitivity. While accurate regression across unseen circuit families remains challenging, the model demonstrates promising capability for estimating relative circuit robustness prior to execution on quantum hardware that is extremely useful for high intensive and expensive workloads.

Navigating with the Wayfinder

The Vegvísir (Icelandic for “wayfinder”) is a magical stave from Icelandic folklore, often called the “Viking Compass,” designed to help its bearer find their way through storms or unknown territory, guiding them physically and spiritually.

I’d say that the closing year was really a rollercoaster due to tariffs concerns, interest rates, wars and geo-political issues.

Nevertheless, we wanted to close the experiments we were planning last year to combine a portfolio with 1/N allocation strategy and pick ten underlying by using a combined ML and mean variance techiques.

The final gain was 31% without recapitalization and a simple investment strategy, buy and hold for one year. In these days we are repeating the underlying selection for 2026 and get back with results in 12 months time, that is neither short nor long term.

This is compared with MVP OOS analysis, same period (violet curve) that lead to about 30% gain with deeper drawdowns. The other defect of the strategy is that it assumes the underlying will behave in the future as they did in the past and so it has no forecasting component in it, that, for example, would have led to losses in 2022.

Have a nice and healthy 2026!